 Jwumasay joo-maJwumasay joo-ma
Jwuma sources, vets, trains and pays a workforce across 12 countries for the categories that are thin in every scraped dataset. Low-resource languages, code-switched speech and imagery from markets the web never photographed properly.
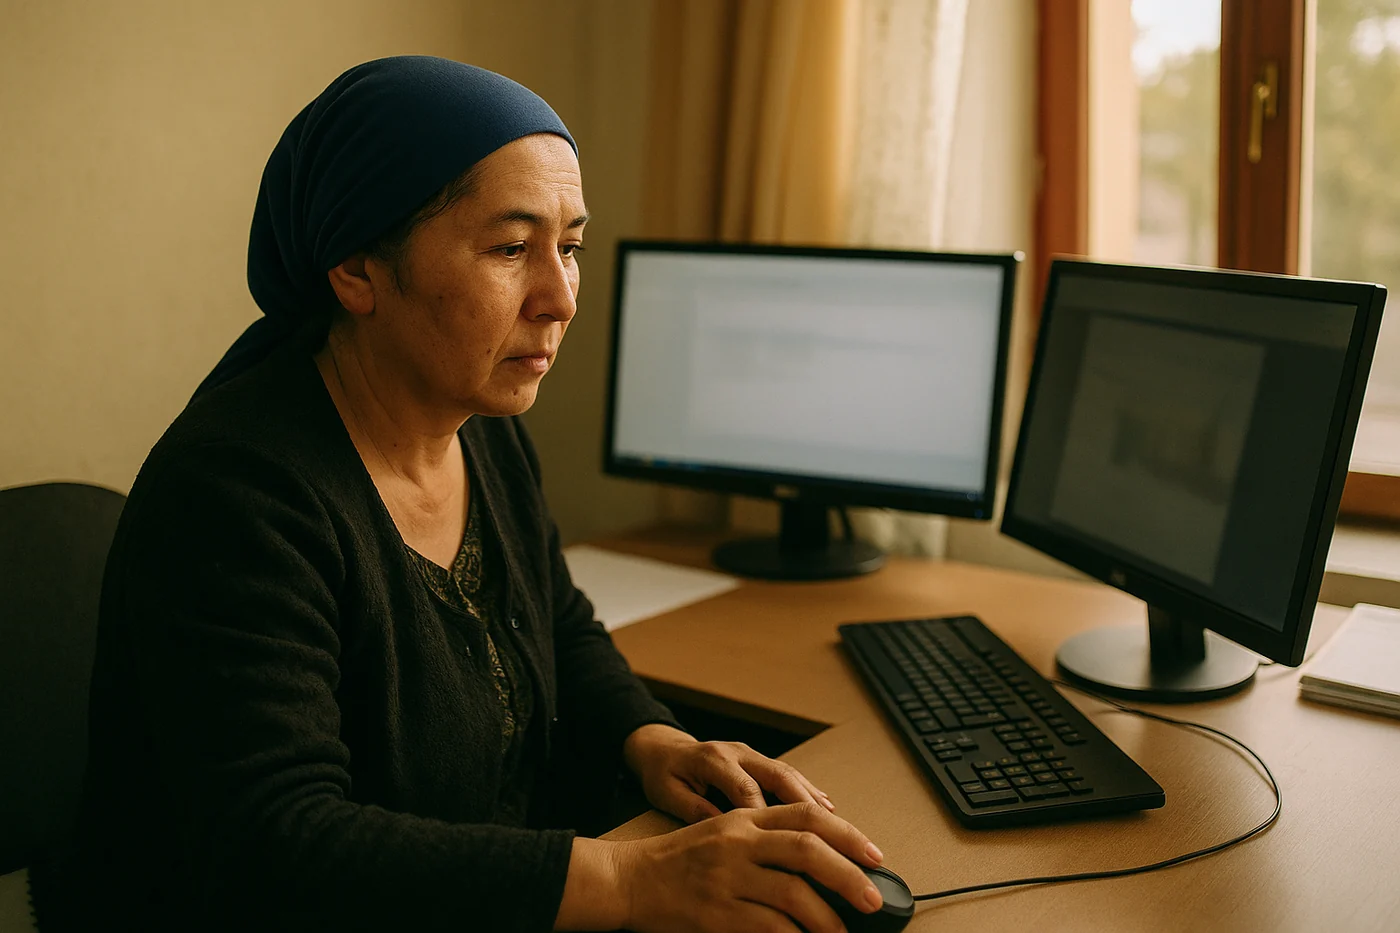
Real-world imagery collected by contributors physically present in the market. EXIF preserved for provenance, capture checklists enforced in-app, consent recorded where people or private property are in frame and validators rejecting blur and duplicates before the batch ever reaches you.
Transcription with speaker turns and code-switch tagging, done by native and fluent speakers sourced in-region. Quality tracked per language rather than pooled into a single misleading average.
Human judgement against a rubric you author. Frozen at batch start so a run is always judged against one auditable standard, with calibration tasks keeping reviewers aligned before production work begins.
The commercial protections that normally live in a contract nobody enforces are implemented in the platform, visible to both sides in real time.
Contributors are paid on our QA acceptance, never on your review timeline. A slow review cycle on your side never becomes an unpaid worker on ours.
Automation may flag or hold work. It cannot reject a submission, decline an applicant or ban an account. Every such decision is made by a named human and written to an audit log.
We store performance metrics only. Personality and behavioural inference about workers is absent from the data model entirely, which means it isn't a setting anyone can quietly flip on later.
A marketplace gives you access to a pool and leaves quality to you. We recruit into your specific project, train contributors against your rubric, review every submission with our own QA team before it reaches you and carry the sourcing and payment burden ourselves. You are the second reviewer, not the first.
You submit a spec, sample, volume and deadline through the client portal. An administrator converts it into a project with a review chain and pay model. From then on the terms run in software: a visible review clock per delivery, deemed acceptance on expiry, a rejection cap with a calibration trigger above threshold, a cure window routing rejections back to the original contributor and a prepaid balance drawing down per accepted task.
Yes, per project, with an allow list or deny list by country, enforced at task assignment rather than documented and hoped for. Presets exist for common compliance regimes. A platform-wide sanctions layer applies underneath your settings regardless of what you configure.
Contributor personal data lives in region-partitioned databases rather than one global pool. Your project data and deliveries are scoped to your organisation. Staff access is role-gated and every mutation writes an audit row. Bulk exports require dual approval from two different administrators.
Acceptance rate, overrule rate, throughput, average handling time and queue depth per project, plus capacity forecasting against your backlog. For higher-assurance batches, gold tasks and consensus review are available.
Dataset packaging exports your accepted deliveries with SHA-256 checksums through signed download URLs and every export is logged. Programmatic access is available through an issued API key.
Bring a spec, a sample or just the gap you've found in your data. We'll tell you honestly whether we can source it and what it would take.